


Overview
Semantic compression for AI conversations. Export from 12 AI platforms. Premium features : Cloud sync and integrity verification.
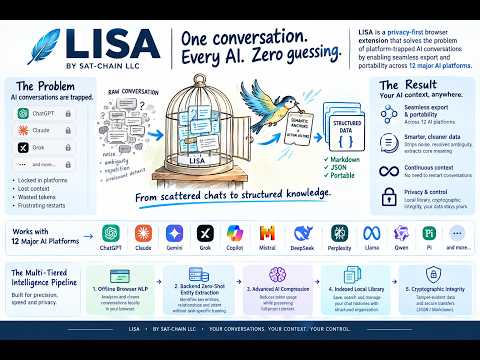
🎯 WHAT IS LISA? A privacy-first browser extension that captures, compresses, and preserves your AI conversations — so you never lose context, never start over, and never get locked into one platform. LISA stands for Linguistic Intelligence Semantic Anchoring — structured data that pre-resolves ambiguity before AI inference begins. 🔒 THE PROBLEM Your AI conversations are trapped. ChatGPT won't let you continue in Claude. Gemini doesn't know what you discussed in Grok. Every platform locks your data in its own silo. No export. No portability. No ownership. You created that knowledge. You should own it. ✨ THE SOLUTION LISA extracts conversations into structured files that work across any AI platform. Inject from your library or upload to Claude, ChatGPT, Gemini, Grok, or any other assistant supported and instantly restore context — including code blocks, decisions, and reasoning. Never Re-Explain Your Project to an AI Again Install LISA, open any AI chat, click capture, and hand the file to a different AI. The first time it picks up exactly where you left off, you'll get it instantly. All new users get 100 free compressions. 🔹🔹🔹 The compression pipeline is essentially a translator. It translates a human conversation into a machine-readable signal. And like any translation, the question is: what carries meaning and what's just grammar holding the sentence together? Noise falls into three categories: Structural glue — "the", "and", "with", "also", "just". These words connect ideas in human language but carry zero semantic signal. An AI reconstructing context from "tokens lean lisa conversation fix session" understands exactly the same thing as "the tokens in the lean lisa conversation to fix the session". The glue is for humans, not machines. Quantifiers without anchors — "all", "two", "some", "real", "many". These modify something but alone they point to nothing. "Two" only has meaning next to what it counts — "two edits" has signal, "two" alone is noise. The concept graph captures "two" as a standalone node because it appears frequently, but it tells the receiver nothing. Narrative scaffolding — "verified", "noticed", "showed", "because". These describe the act of discovering something, not the thing itself. "Never verified because you didn't reload" is a story about what happened. "Always use getattr() on Stripe objects" is a rule. The receiver needs rules, not stories. Signal is the opposite — words that are definite, specific, and independently meaningful: Domain nouns: "tokens", "compression", "anchor", "harness" — each one names a thing Action verbs in context: "fix", "strip", "merge" — each one names what happened Named entities: "LISA", "SemanticAnalyzer", "Stripe" — each one names who/what When you stack signal words together — "tokens lean lisa compression fix session" — they form a semantic skeleton that an AI can expand back into full understanding. The stopword stripping isn't destroying information, it's removing redundancy that the receiver will regenerate automatically from context. This is literally what you do as a translator. You don't translate word-for-word from Arabic to English — you translate meaning. Some Arabic particles have no English equivalent and get dropped. Some English articles have no Arabic equivalent and get added. The meaning crosses, the grammar adapts. That's what LISA does between human language and machine language. The deeper insight: the frequency filter catches what the static list can't. Any word appearing in >25% of sentences is probably glue for this specific conversation, even if it's a real noun in other contexts. "File" is meaningful in a cooking conversation, noise in a coding session where every other sentence mentions files. AI doesn't read words. It reads tokens — subword fragments produced by a tokenizer. "Understanding" is one token. "ACME-Tech Co." is three. Every token costs compute, and raw conversation is full of waste: "sure", "got it", "thanks" burn tokens that carry zero meaning. Pronouns like "he", "it", "the tool" force the AI to spend inference work guessing what they refer to. The same entity name repeated forty times costs forty times the tokens. And none of this ambiguity was yours — it's an artifact of how conversation flows, not what you meant. LISA's compression pipeline attacks each layer of that waste. Salience routing scores every turn by how central it is to the conversation's meaning and drops the noise. Entity aliasing replaces repeated names with short aliases backed by a glossary — "ACME-Tech Co." appears once in full, then as "ATC" for the rest, with zero ambiguity. Coreference resolution rewrites "he said it was done" as "Amar said the parser was done" before the AI ever sees it. And real token counts (via tiktoken, the same tokenizer the models use) replace character-based guesses so you know exactly what you're saving. The result: the AI gets a pre-disambiguated, leaner input where every token carries meaning. 🌐 SUPPORTED PLATFORMS — 12 AI ASSISTANTS Export from all major AI platforms with full role attribution including Claude Code. 🚀 KEY FEATURES 📤 ONE-CLICK EXPORT — Click the floating LISA button on any supported platform. Virtualized conversations (ChatGPT, Grok, Perplexity) swept automatically. Perplexity uses API-first capture with DOM fallback for complete extraction. 📎 INJECT FROM LIBRARY — Select any saved conversation and inject it as markdown into your active AI tab. Continue exactly where you left off, on any platform. 🧠 SEMANTIC INTELLIGENCE PIPELINE — Three tiers, no LLM required for the first two: • Tier 1 (free, offline): NLP in your browser via compromise.js — entity recognition (people, organizations, places), basic pronoun resolution, scored semantic anchors, and action vector extraction on every capture. Goes beyond regex pattern matching to dictionary-based language analysis. • Tier 1.5 (free API): GLiNER zero-shot entity extraction and fastcoref coreference resolution on the backend — identifies entities by type at runtime and links pronouns to their referents, at zero LLM cost. • Tier 2 (premium): Full AI compression with salience routing (drop low-value turns), entity aliasing (glossary-backed shorthand), and semantic disambiguation before the LLM compresses your text. Real token counts via tiktoken. 💾 FOUR EXPORT FORMATS 🧠 LISA JSON (Semantic) — Per-message entity and concept extraction. Graph-based TextRank concept scoring with code-aware preprocessing strips code blocks, splits camelCase, and filters noise before ranking. Relationship types defined (requires, implements, excludes, references, triggers, supports, contradicts, supersedes) — coverage expanding with each release. 🔗 LISA-V (Verbatim+) — Block-level JSONL with SHA-256 hashes and Merkle root for tamper-proof integrity 🤖 AI Compressed — Backend semantic compression with salience routing, entity aliasing, disambiguation, action vectors, and reconstruction protocol. Verified token counts via tiktoken. (premium) 📋 Markdown — Clean .md export, ready to inject or upload into any AI chat ⚡ INDEXED LIBRARY Fast-loading library with indexed storage. Browse, search, and manage your saved conversations. Full snapshot data loads on demand — the popup stays responsive even with hundreds of saved sessions. 📋 CROSS-PLATFORM CONTEXT TRANSFER Right-click any text → "Copy as LISA Context" — wrapped with source platform and metadata. Paste into any AI chat instantly. 🤖 LISA MEMORY SERVER (MCP) Six tools for AI agents: 🔍 lisa_search_context — Search your library by keyword, with semantic search when embeddings are available (free) 📦 lisa_get_handoff_pack — Retrieve full context packs (free) 💾 lisa_save_snapshot — Persist agent sessions (free) 📈 lisa_get_usage — Check tier and credits (free) 🗜️ lisa_compress — AI semantic compression with full pipeline (metered) 📊 lisa_generate_report — Governance-verified reports (metered) Works with Claude Code, Claude Desktop, Cursor, and any MCP client. 📚 LIBRARY 💾 Saves — LISA-V, and local compressed snapshots 🤖 AI — Backend AI-compressed snapshots Browse, search, inject into active AI tabs. Zero cloud dependency. 🧩 AMBIGUITY CATEGORIES LISA targets 10 categories of conversational ambiguity: Referential, Temporal, Priority, Completion, Social noise, Reasoning, Role, Dependency, State, and Relevance. Tier 1 handles social noise filtering and basic referential resolution. Tier 1.5 adds entity-level referential and coreference resolution. Tier 2 applies full semantic routing to address salience and relevance. Coverage deepens with each release. 🌍 MULTILINGUAL — 10 languages with full RTL support: English (default), Arabic (+ RTL support), Hebrew (+ RTL support), French, Chinese, Japanese, Korean, Cyrillic (Russian and related) 🔬 SEMANTIC ENRICHMENT — Scored Semantic Anchors (top conversation moments ranked by importance), Action Vectors (extracted decisions and commands), File Detection, Git References, URL Extraction. Enrichment runs on all 12 platforms. ✂️ SELECTION EXPORT — Select text, right-click, export or copy as LISA Context. 📖 HOW TO USE 1️⃣ CAPTURE — Click the floating LISA button 2️⃣ SAVE — Download as JSON/JSONL/MD or save to your library 3️⃣ CONTINUE — Inject from library (📎) or upload to any AI and say "continue where we left off" 💡 WHO IS LISA FOR? • Developers — Save coding sessions, transfer context mid-project. Connect LISA Memory Server to Claude Code or Cursor for persistent AI memory. • Researchers — Cryptographic verification, audit trails, tamper-proof integrity via Merkle root. • Business professionals — Client documentation, compliance records, governance-verified reports via LISA Nexus. • Multilingual users — 10 languages auto-detected and correctly tagged. • Students — Build a personal AI knowledge library across platforms. • Anyone switching AI platforms — Take your full conversation history with you. 💰 PRICING FREE — Always available • 100 welcome compressions (then 5/day) • All 12 platforms, local library, offline NLP enrichment, multilingual detection • Right-click Copy as LISA Context PAY AS YOU GO — No subscription, credits never expire 💳 100 credits / $1 • 500 credits / $4 • 1,000 credits / $7 PREMIUM — $9.99/month or $89.99/year (save $30) One subscription. Two products: 🔹 LISA — Unlimited exports, saves, LISA Hash, MCP access, full semantic pipeline 🔹 LISA Nexus — Governance-verified compression, reports, cloud sync, share links, up to 12 semantic anchors, priority AI processing 🔒 PRIVACY FIRST ✅ 100% local processing — all extraction and Tier 1 NLP happens in your browser ✅ Zero server uploads unless you explicitly sync to LISA Nexus ✅ No content tracking, no analytics on conversations ✅ Open, portable JSON/JSONL/MD format — no vendor lock-in 🛡️ TECHNICAL SPECS Version 0.52.7 • Manifest V3 • SHA-256 + Merkle root integrity • 12 platforms with unified LISA-V parser • 10 languages • Offline NLP: compromise.js entity recognition + pronoun resolution • Backend NLP: GLiNER zero-shot NER + fastcoref coreference resolution • Compression pipeline: salience routing → entity aliasing → disambiguation → LLM → tiktoken verification • MCP Server (6 tools, streamable HTTP + stdio) • Embeddings: BGE-small-en-v1.5 for semantic search (when available) • Indexed snapshot storage 🏢 ABOUT SAT-CHAIN LLC Built by SAT-CHAIN LLC, founded by Amar Dahmani — a professional translator with 25 years across English, French, and Arabic. The consumer suite: LISA Core (capture), LISA Nexus (govern & compress), LISA Memory Server (MCP for AI agents), Inference Shield (coming soon). Every other tool saves what was said. LISA saves what was meant. 📬 contact@sat-chain.com • 🌐 sat-chain.com © 2026 SAT-CHAIN LLC
5 out of 53 ratings
Details
- Version0.52.7
- UpdatedOctober 1, 2026
- FeaturesOffers in-app purchases
- Offered bySAT-CHAIN LLC
- Size317KiB
- LanguagesEnglish (United States)
- DeveloperDahmani Amar
Cite Sonelgaz - Bt 2 - Appt 10 Bab Ezzouar Algiers 16024 DZEmail
amar.dahmani@sat-chain.comPhone
+213 666 00 46 47 - TraderThis developer has identified itself as a trader per the definition from the European Union and committed to only offer products or services that comply with EU laws.
Privacy

LISA - AI Chat Exporter for Claude, ChatGPT & More has disclosed the following information regarding the collection and usage of your data. More detailed information can be found in the developer's privacy policy.
LISA - AI Chat Exporter for Claude, ChatGPT & More handles the following:
This developer declares that your data is
- Not being sold to third parties, outside of the approved use cases
- Not being used or transferred for purposes that are unrelated to the item's core functionality
- Not being used or transferred to determine creditworthiness or for lending purposes
Support
For help with questions, suggestions, or problems, please open this page on your desktop browser