


概述
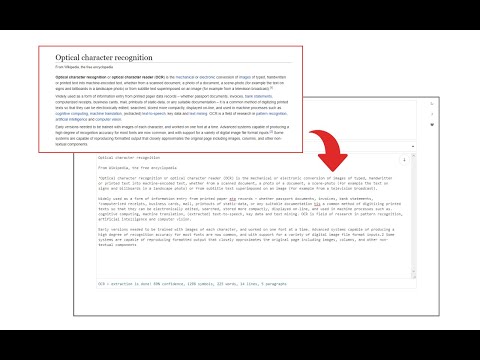
Easily get words out of an image with OCR engine!
Image Reader (OCR) extension helps you easily get words out of any image. It uses two different open-source OCR engines. The 1st engine is called Tesseract. Tesseract.js is an open-source JavaScript library and is made via an Emscripten port of the famous Tesseract OCR Engine written in C and C++. Please visit (https://github.com/naptha/tesseract.js) to get more info. The 2nd engine, called Granite Docling, is developed by IBM (https://huggingface.co/ibm-granite/granite-docling-258M). Please note that when you choose IBM Granite Docling, the app needs to download training data (~1200MB) for the AI engine. So please be patient while it is loading. To work with this addon, simply open the addon's interface and load your image via the file selector (top section). Before using the addon, please make sure to select the appropriate OCR engine and language. For Tesseract, the default OCR language is set to English. For Granite Docling, you do not need to set a language; just select the desired backend (CPU or GPU) and wait for the app to load completely. Note: For the Tesseract OCR engine, this addon uses the "https://github.com/naptha/tessdata/tree/gh-pages/" GitHub repo to fetch language data required for the OCR operation. For the IBM Granite Docling, it uses "https://huggingface.co/onnx-community/granite-docling-258M-ONNX" to fetch training data required for the OCR operation. Both language data packs are very large and cannot be included in the addon package. To report bugs, please fill out the bug report form on the extension's homepage (https://mybrowseraddon.com/image-reader.html).
3.6 星(5 星制)27 个评分
详情
- 版本0.2.0
- 上次更新日期2025年11月10日
- 提供方Sevina
- 大小13.19MiB
- 语言English
- 开发者
邮箱
sevina.lucia@gmail.com - 非交易者该开发者尚未将自己标识为交易者。欧盟地区消费者须知:消费者权利可能不适用于您与该开发者达成的合约。
隐私权
该开发者已声明,您的数据:
- 不会因未获批准的用途出售给第三方
- 不会为实现与产品核心功能无关的目的而使用或转移
- 不会为确定信用度或放贷目的而使用或转移
支持
若有任何疑问、建议或问题,请访问开发者的支持网站